WAV Chunk Reference
I put together this page in the hopes that it will serve as a reference for anyone wanting information on what the various chunks of data within a WAV file contain and what standards may define them.
A WAV file not only contains audio samples, but also can hold various types of non-audio metadata such as time code, cue markers, loudness info, sampler loops, recording description data, or metadata specific to a particular program/app. Most programs only show a small portion of what’s inside a WAV. As for the info they don’t manage, they at best ignore…and at worst, may entirely remove it.
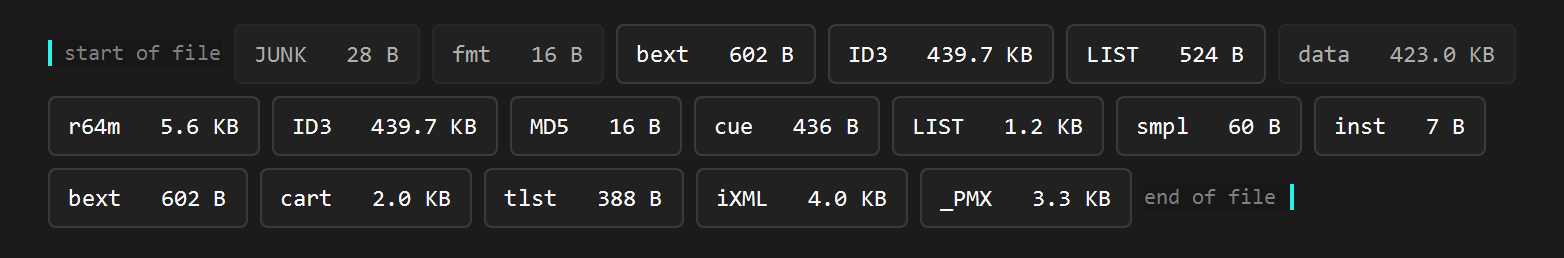
Below you will learn how to identify every chunk written within a WAV or BWF (Broadcast Wave file). You’ll find an explanation of what info each chunk carries and what specification or source defines it, if any. Lastly, each section points out implementation details and any common software mistakes.
Who might find this reference useful? Developers writing parsers, archivists, audio engineers, those investigating metadata survival/history, or just someone technically curious.
Entries are grouped according to their function or purpose. They all receive one of four label types (see below) that explain who or what defines their specifications. This could be a formal standard written by a governing body on down to the reverse-engineering of a private spec by a group of enthusiasts.
So what makes a WAV file a WAV file? In short, a WAV file is an audio container format based on Microsoft and IBM’s RIFF specification. It stores audio data-most commonly uncompressed PCM-along with structural information in a series of data blocks called chunks. The two essential chunks are fmt for the audio format and data for the audio samples. Everything else is optional, like the metadata.
How standardization is labeled
Below is a chart showing the four standardization labels. Each chunk listed in the various tables beneath it will have one of these four labels under the “STANDARDIZATION” heading.
- Formal standardA formal standards organization publishes an authoritative document that defines the details of these chunks. Examples shown on this page include Microsoft/IBM, EBU, ITU, AES, and CIPA.
- Published specThese chunks have no formal standardization. However, they are defined by a publicly available specification from either a vendor or community group. Examples are Gallery's iXML specification or Adobe's XMP file-storage specification.
- ConventionNo specification defines the RIFF chunk itself, yet it has established support from multiple independent writers. Sometimes the data inside has a formal specification, but its WAV wrapping does not.
- Vendor-specificThe format belongs to a single company or developer and was never standardized or published for general use. Some of these have been reverse-engineered by the community, but that doesn't change who controls the format. This reference shows the chunk's presence and general purpose only.
Reading the four-character codes
WAV files use the four-character code, or FourCC, to identify audio format and data chunks, and any other chunks specific to the audio format. Spaces are allowed as padding for a FourCC with less than four characters, so a three letter FourCC would be valid, as in the case of fmt, for example. Notice the space trailing the fmt. The padding must be on the right with blank characters. And don’t overlook letter case. FourCC values are case-sensitive. So axml and AXML are not the same. RIFF conventionally uses uppercase identifiers for registered chunk types that can apply across RIFF formats, including RIFF, LIST, and JUNK, while lowercase identifiers are generally used for form-specific chunks, such as WAVE’s fmt and data. Later extensions do not always follow this convention. Lastly, when it comes to LIST / INFO and LIST / adtl, LIST is the chunk ID while INFO & adtl are list types stored at the beginning of the LIST chunk’s data.
Core RIFF structure
This section covers the structures that make up a basic WAV file: the container/header, the audio format description, the audio sample data, auxiliary format information, and large-file extensions for files larger than four gigabytes.
| Chunk | Carries | Defining specification | Standardization |
|---|---|---|---|
RIFF | Little-endian WAV container | Microsoft / IBM RIFF (MMPIDS 1.0, 1991) | Formal standard |
RIFX | Big-endian RIFF container, usable with any RIFF form | Microsoft / IBM RIFF (MMPIDS 1.0, 1991) | Formal standard |
RF64 | Over-4GB WAV container (EBU) | EBU Tech 3306 | Formal standard |
BW64 | Over-4GB file identifier (ITU) | ITU-R BS.2088 | Formal standard |
fmt | Codec, channel count, sample rate, bit depth; the EXTENSIBLE form adds a channel mask and a format GUID | Microsoft / IBM RIFF and WAVE; WAVE_FORMAT_EXTENSIBLE is a later Microsoft addition | Formal standard |
data | The audio samples | Microsoft / IBM RIFF and WAVE | Formal standard |
fact | Sample count and file-dependent information for non-PCM and compressed data | Microsoft / IBM RIFF and WAVE | Formal standard |
ds64 | The 64-bit size table that an RF64 or BW64 file uses in place of the 32-bit header sizes | EBU Tech 3306; ITU-R BS.2088 | Formal standard |
RF64 and BW64, a problem will occur if a parser reads the 32-bit header instead of the ds64 chunk. It will read it as nonsense. The RIFF size fields for both types are set to 0xFFFFFFFF. This indicates that the sizes are stored in the ds64 chunk. The ds64 table is the authority here. The second confusion involves the fmt chunk and its WAVE_FORMAT_EXTENSIBLE form. Don’t confuse the two…they’re not interchangeable. Multichannel and high-bit-depth files rely on the extensible form's channel mask and format GUID. The base header has no way to store that info.Broadcast Wave and EBU metadata
Broadcast Wave (BWF) is an extension of the WAV format. It was developed by the European Broadcasting Union (EBU) for professional audio production and broadcasting. The bext chunk sits at the heart of the standard. The EBU also defines a numbered series of supplement chunks that add other types of metadata. The AES defines a separate chunk for radio automation.
| Chunk | Carries | Defining specification | Standardization |
|---|---|---|---|
bext | Description, originator, origination date and time, time reference, SMPTE UMID (version 1 and later), EBU R 128 loudness (version 2), and coding history | EBU Tech 3285 (defining); ITU-R BS.1352 Annex 1 | Formal standard |
ubxt | UTF-8 multilingual broadcast extension, a companion to bext | ITU-R BS.1352 Annex 1 | Formal standard |
mext | MPEG-1 audio extension (Layer I/II in practice) | EBU Tech 3285 Supplement 1 | Formal standard |
qlty | Capturing report: a quality report and a cue sheet | EBU Tech 3285 Supplement 2 | Formal standard |
levl | Peak-envelope overview data | EBU Tech 3285 Supplement 3 | Formal standard |
link | XML linkage across a set of related BWF files | EBU Tech 3285 Supplement 4 | Formal standard |
axml | Arbitrary XML 1.0, most often Audio Definition Model (ADM) data | EBU Tech 3285 Supplement 5; ITU-R BS.2088-2 section 5 for BW64 | Formal standard |
dbmd | Dolby metadata | EBU Tech 3285 Supplement 6 | Formal standard |
cart | Radio traffic and continuity data for broadcast automation | AES46-2002 | Formal standard |
r64m | RF64 marker chunk, a cue replacement for large files | EBU Tech 3306 | Formal standard |
What tools get wrong. The bext chunk has changed over time, so you must pay attention to its version number. Version 0 was introduced in 1997 and contains the original fields along with coding history. Version 1 has been in use since 2001. It adds the 64-byte SMPTE UMID. Lastly, Version 2 came out in 2011. It adds the EBU R 128 loudness fields. Those loudness fields obviously do not exist in versions 0 or 1. The same bytes are reserved there and are supposed to contain zeros. If a particular program reads them as loudness values anyway, then the loudness values are meaningless. Also, if a writer fails to zero the reserved area, it may leave actual garbage in those bytes.
mext is another chunk that can be misunderstood if you’re not careful. The MPEG coding information itself is stored in the MPEG extension to the fmt chunk and in the fact chunk. The broadcast-specific information is added by the mext chunk on top of that. This includes ancillary-data information, frame-size information, and homogeneity flags. Keep in mind that it does not replace the MPEG information stored in the other chunks. Also, EBU Supplement 1 refers to MPEG-1 audio rather than specifically to Layer 2. So a reader keying on "Layer 2" alone is working from a narrower label than the spec uses.
Lastly, cart contains more than the URL and tag text that many tools expose. AES46-2002 also defines eight post-timer entries along with a reserved area between the level-reference field and the URL. Those post-timers are part of the defined structure, regardless of whether a particular program chooses to show them or not.
Object audio and the Audio Definition Model
The Audio Definition Model (ADM) describes object-based and immersive audio. Its descriptive metadata is XML, which is usually carried in the axml chunk listed above. A separate chunk maps the file’s audio tracks to the ADM description.
| Chunk | Carries | Defining specification | Standardization |
|---|---|---|---|
chna | A track map linking each audio track to ADM identifiers (track UID, track and channel format, pack format) | ITU-R BS.2088-2 section 8; semantics from ITU-R BS.2076 | Formal standard |
bxml | Compressed (gzip) XML, an alternative to axml | ITU-R BS.2088-2 section 6 | Formal standard |
sxml | Segment-associated XML; Serial ADM (S-ADM) is its principal payload | ITU-R BS.2088-2 section 7 (chunk); ITU-R BS.2125-1 (S-ADM payload) | Formal standard |
sxml as the general vehicle and S-ADM as one of the payloads that can ride inside of it. Treating the two as equivalent reverses the relationship. BS.2088-2 defines sxml as a container for segment-associated XML of any kind, with S-ADM listed as the principal named payload. BS.2125-1, by contrast, specifies the S-ADM format itself but never names or defines the chunk that carries it.
FourCC identifiers are case-sensitive. Legitimate ADM data can appear under the lowercase axml FourCC. However, an uppercase AXML variant shows up in some tooling. The two codes should be recognized separately and not merged or treated as interchangeable.
Cue points, regions, and sampler data
This family marks positions and ranges in the audio data, names them, and describes how a sampler should play the file. Most of it is part of the original 1991 baseline; the sampler and instrument chunks were added in Microsoft's 1994 Multimedia Standards Update.
| Chunk | Carries | Defining specification | Standardization |
|---|---|---|---|
cue | Cue points, as bare sample positions with identifiers | Microsoft / IBM RIFF (MMPIDS 1.0, 1991) | Formal standard |
plst | A playlist, an ordered play sequence of cue points | Microsoft / IBM RIFF (MMPIDS 1.0, 1991) | Formal standard |
LIST / adtl | Associated-data list: the container for the cue annotations below | Microsoft / IBM RIFF (MMPIDS 1.0, 1991) | Formal standard |
labl | A text label for a cue point | Microsoft / IBM RIFF (MMPIDS 1.0, 1991) | Formal standard |
note | A text note for a cue point | Microsoft / IBM RIFF (MMPIDS 1.0, 1991) | Formal standard |
ltxt | Labeled text spanning a range of samples | Microsoft / IBM RIFF (MMPIDS 1.0, 1991) | Formal standard |
file | Information about a file tied to a cue point; the meaning is application-specific | Microsoft / IBM RIFF (MMPIDS 1.0, 1991) | Formal standard |
smpl | Sampler data: unity note, fine tuning, loop points, SMPTE format | Microsoft Multimedia Standards Update (1994) | Formal standard |
inst | Instrument data: unshifted note, gain, key and velocity ranges | Microsoft Multimedia Standards Update (1994) | Formal standard |
slnt | A run of silent samples, used within a wave list | Microsoft / IBM RIFF and WAVE | Formal standard |
wavl | A wave list: an alternating sequence of data and slnt chunks | Microsoft / IBM RIFF and WAVE | Formal standard |
cue chunk. The labels, notes, and timed text are found in a LIST chunk of type adtl. Each entry uses its identifier to link back to the matching cue point. If an editor displays cue points as anonymous markers, it means the program read the cue chunk and ignored adtl or that the file had no adtl at all.Tagged text and consumer metadata
The oldest and most common metadata in WAV files: simple tagged text, plus the Exif-audio list used by some cameras and recorders.
| Chunk | Carries | Defining specification | Standardization |
|---|---|---|---|
LIST / INFO | Tagged text fields, each a four-character tag: title (INAM), artist (IART), comment (ICMT), genre (IGNR), creation date (ICRD), and many more | Microsoft RIFF Multimedia File Reference | Formal standard |
LIST / exif | Exif-audio list (list type exif): version (ever), related image (erel), time (etim), maker (ecor), model (emdl), maker note (emnt), user comment (eucm) | CIPA DC-008-2012 section 5.6.3 | Formal standard |
emnt (maker note) and eucm (user comment) are two of its fields to watch. eucm tells you how the text is encoded with its first eight bytes. Don’t fall into the trap by assuming it is ASCII. A reader must check those bytes for ASCII, JIS, Unicode, or undefined. For emnt, just report its existence and carry on, as there’s nothing for you to decode due to it being a manufacturer-specific block of data. Production metadata: iXML
iXML is an open standard for embedding location recording metadata that is published by Gallery (UK). It’s also the home for several vendor-defined extensions, such as the Sony ASWG iXML Extension and Steinberg’s fields. These two both live inside the iXML payload as nested elements instead of as separate chunks.
| Chunk | Carries | Defining specification | Standardization |
|---|---|---|---|
iXML | Production-sound XML: scene, take, sound roll, project, sync and speed, and a track list, plus vendor extension blocks | Gallery iXML Specification, Revision 3.01 (Gallery UK, October 2021) | Published spec |
oXML | A nullified former iXML header, renamed so it is no longer read as active iXML | Gallery iXML Specification (invalidation guideline) | Published spec |
oXML shouldn’t be parsed. Sometimes a tool needs to lengthen the XML document structure because there is no space to fit data that needs to be added. When this happens, it’s quicker to just invalidate the original header and write the new iXML chunk at the end of the file. A faithful reader labels it as a former iXML chunk and leaves it alone. Embedded standards: XMP and ID3
Because a WAV file is built on RIFF’s flexible container structure, two metadata standards from outside the WAV world are commonly carried as chunks: Adobe’s XMP and the ID3 tag familiar from MP3.
| Chunk | Carries | Defining specification | Standardization |
|---|---|---|---|
_PMX | An Adobe XMP packet (the Extensible Metadata Platform) | Wrapping: Adobe XMP Specification Part 3, Storage in Files (January 2020). Payload: Part 1, ISO 16684-1 | Published spec |
ID3 / id3 | An embedded ID3v2 tag: attached picture (APIC), rating (POPM), and text frames | Payload: ID3v2.3 and ID3v2.4. RIFF wrapping: convention, no standards-body definition | Convention |
_PMX, not XMP_, which would seem logical. The reason for the flip is a byte-order bug in the original implementation, as documented by Adobe. You can find XMP_ in a different container format. It’s used as the XMP atom in QuickTime.Padding and miscellaneous chunks
This section is a bit of a catch-all. Three of the chunks (JUNK, PAD, FLLR) are used as filler or reserved space within the WAV file. The other four (CSET, DISP, MD5, PEAK) serve unrelated purposes that don’t fit neatly elsewhere.
| Chunk | Carries | Defining specification | Standardization |
|---|---|---|---|
JUNK | Generic filler; also used as the reserved placeholder that an RF64 or BW64 file overwrites with ds64 | Microsoft / IBM RIFF (the placeholder use is derivative) | Formal standard |
PAD | Padding of arbitrary size, used to preserve alignment | Microsoft Multimedia Standards Update (1994) | Formal standard |
CSET | Character set: code page, language, dialect | Microsoft / IBM RIFF | Formal standard |
DISP | A display hint: a title as text, or an icon as a device-independent bitmap | Microsoft Multimedia Standards Update (1994) | Formal standard |
FLLR | Filler used to align the start of audio data | Convention; associated with Pro Tools | Vendor-specific |
MD5 | A 16-byte checksum of the audio data | Convention; documented by FADGI and BWF MetaEdit | Convention |
PEAK | An editor's peak-overview cache for fast waveform drawing | No formal specification; used by Adobe and others | Convention |
What tools get wrong. PEAK and BWF’s levl chunk both describe a waveform envelope. PEAK is an editor’s own peak-overview cache. Mixing them up will produce wrong overviews. Also, a known incompatibility exists between some tools' PEAK data and other libraries.
Vendor and proprietary chunks
A WAV file can also contain chunks written by some of the various editors, samplers, recorders, and other audio software. They’re not standardized chunks, but they belong to a particular company, developer, or product. What is known about them varies quite a bit. Some have been reverse-engineered and documented, while others we still know very little about. Regardless of how well or poorly they’re understood, the goal here is to document that they exist. If known, the software or hardware they are associated with and what they appear to contain will also be shown.
| Chunk | Carries | Defining specification | Standardization |
|---|---|---|---|
acid | ACIDized-loop information: tempo, key, beat count, and meter | No published specification; layout is community-reverse-engineered | Vendor-specific |
strc | Slice and transient markers used alongside acid | No published specification; community-observed | Vendor-specific |
ovwf | An overview-waveform cache, reportedly associated with Apple Logic Pro | No published specification | Vendor-specific |
SMED | Soundminer editing data; opaque | No published specification (Soundminer) | Vendor-specific |
NMIX | An opaque binary chunk, reportedly associated with NetMix sound-library metadata | No published specification | Vendor-specific |
RLND | Roland sampler data (the SP-404 family); the chunk is padded so the audio data begins at a fixed offset | No published specification (Roland); a community decoder exists | Vendor-specific |
ResU | Apple Logic Pro project data, stored as compressed JSON (tempo, time signature) | No published specification (Apple Logic Pro) | Vendor-specific |
minf | Media information, associated with Steinberg Cubase and Nuendo | No published specification | Vendor-specific |
elm1 | Element data, associated with Steinberg Cubase and Nuendo | No published specification | Vendor-specific |
tlst | A trigger list: triggers that fire playback of cue points or playlist entries. Written by Sonic Foundry Sound Forge | No formal specification; documented in the Sound Forge 4.5 manual (proposed by Sonic Foundry, never registered with Microsoft) | Vendor-specific |
regn | Region markers, associated with Sound Forge | No published specification | Vendor-specific |
rpp1 / rpp | Project-state data, associated with Cockos Reaper | No published specification | Vendor-specific |
afsp | Metadata written by the AFsp audio toolkit | No published specification; toolkit-observed | Vendor-specific |
olym | Recorder metadata, associated with Olympus devices | No published specification; tool-observed | Vendor-specific |
What tools get wrong. The RLND chunk has an unusual structural quirk. It contains padding that places the audio data at a predetermined offset. If a parser ignores this padding, then it could read the wrong data as audio.
Related formats that are not WAV chunks
You should be aware that there are a few four-character codes that are NOT WAV chunks. They are different file formats altogether. For example, FORM is found at the beginning of an AIFF or AIFF-C file. fLaC is another one. It identifies a FLAC file. And OggS marks the beginning of an Ogg stream. Then there’s Sony’s Wave64. It’s related to WAV, but IS its own container. Instead of the RIFF/WAV four-character codes, it uses 128-bit GUIDs to identify its structures. This info is included here mainly to avoid confusion if you happen to come across them while inspecting audio files. Everything else on this page concerns chunks you can actually find inside a RIFF WAV file.
Specifications referenced
- RIFF and WAVE (baseline): Microsoft and IBM, Multimedia Programming Interface and Data Specifications 1.0 (1991)
- RIFF additional chunks: Microsoft Multimedia Standards Update, New Multimedia Data Types and Data Techniques, Revision 3.0 (1994), which defines
PAD,DISP, and the sampler and instrument chunks;JUNKand the cue, playlist, and associated-data family are part of the 1991 baseline - LIST / INFO: Microsoft RIFF Multimedia File Reference
- Broadcast Wave (bext) and supplements: EBU Tech 3285, Version 2 (2011), with supplements 1 (
mext), 2 (qlty), 3 (levl), 4 (link), 5 (axml), and 6 (dbmd); EBU R 85-2004 for production usage - RF64 and MBWF: EBU Tech 3306
- bext and mext, ITU adoption: ITU-R BS.1352 (Annex 1 for
bextandubxt) - BW64 chunks: ITU-R BS.2088 (
ds64,axml,bxml,sxml,chna) - Audio Definition Model: ITU-R BS.2076 (the model) and ITU-R BS.2125 (Serial ADM)
- Radio cart: AES46-2002
- Exif-audio list: CIPA DC-008-2012 (Exif 2.3), section 5.6.3
- ID3 payload: ID3v2.3 and ID3v2.4 (id3.org)
- XMP: Adobe XMP Specification Part 1 (ISO 16684-1) for the payload, and Part 3, Storage in Files (January 2020), for the WAV chunk wrapping
- iXML: Gallery iXML Specification, Revision 3.01 (Gallery UK, October 2021)
- ASWG extension: Sony ASWG iXML Extension v1.1 (github.com/Sony-ASWG/iXML-Extension)
About this reference
This reference is compiled and maintained by the developer behind WAVScribe, a WAV metadata editor, and the free, read-only WAVScribe Viewer. If you spot an error or a chunk that should be added, corrections are welcome through the contact page.